How Smritea turns text into memories: facts, skips and duplicates
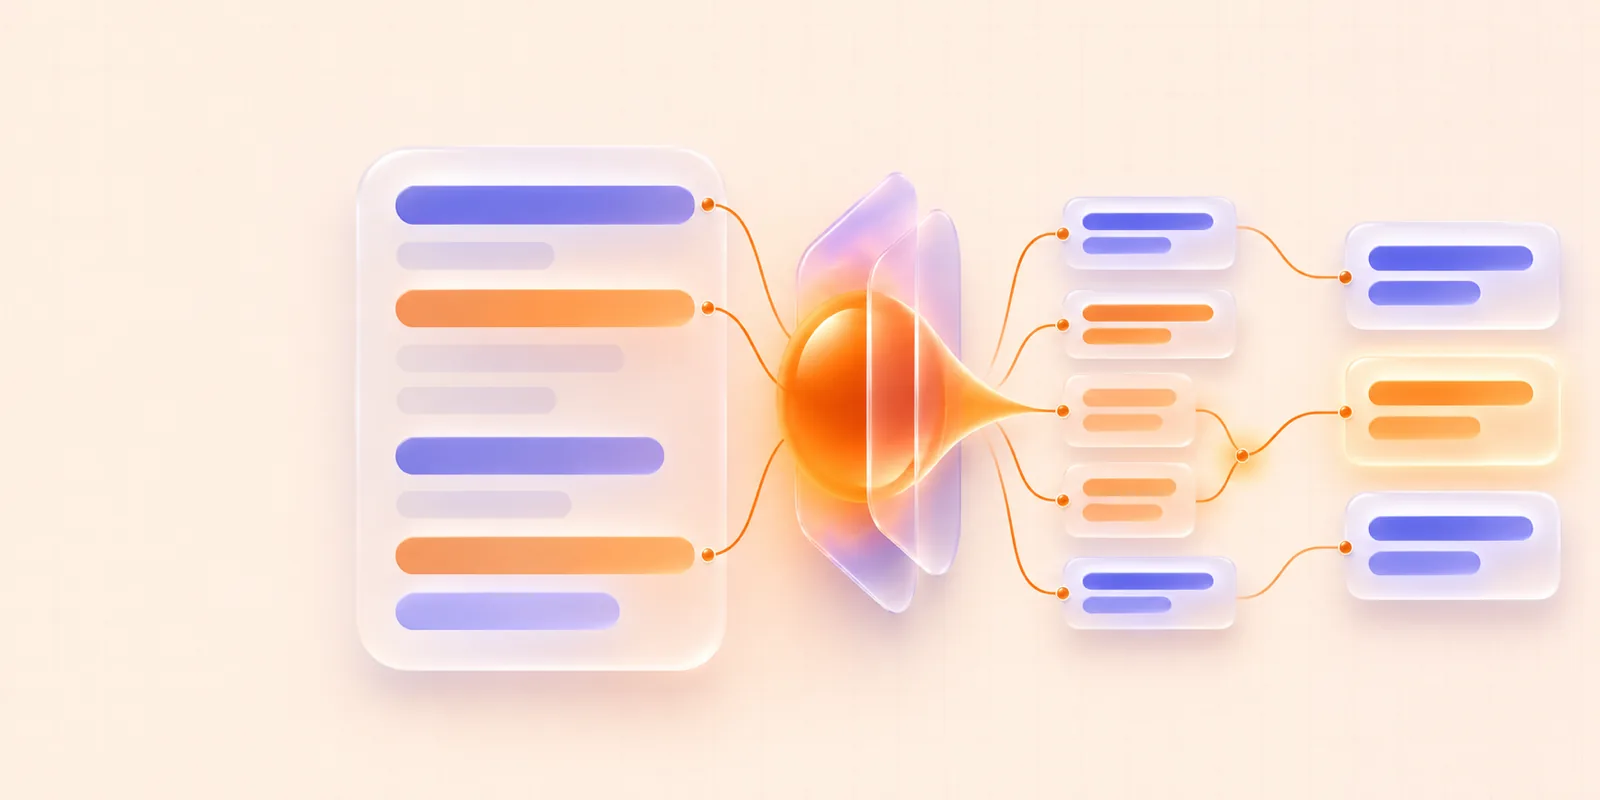
Fact extraction is the step that turns the text you send to add into separate memories. A memory is one stored fact. How many memories a call creates depends on the storage engine you chose for the app.
Two storage engines, two results
You pick the storage engine when you create the app. You cannot change it after the app has memories.
| Quick Search app | Deep Search app | |
|---|---|---|
| Splits text into separate facts | No | Yes |
Memories per add call | One, holding your text as sent | Zero or more, one per fact |
| Skips text with nothing to remember | No | Yes |
| Builds entities and relationships | No | Yes |
A Quick Search app runs no language model on add. It stores your text as sent, which keeps cost low for high-volume apps.
The four extraction steps
A Deep Search app runs the text through four steps.
- A language model splits the text into short, separate facts. A fact can carry a date, tags and an importance score.
- Smritea compares each fact with the memories you already have. Each fact gets one verdict: new, same or update.
- New facts become new memories. Smritea skips a same fact. An update fact merges into the existing memory.
- In the background, Smritea finds people, places and other entities in the new memories and links them in a knowledge graph.
A call can succeed and store nothing
Three outcomes are normal, and none is an error.
| Case | What you see |
|---|---|
| The text holds nothing worth keeping, such as a greeting | memories is empty and explicit_skip is true |
| Every fact matches a memory you already have | memories is empty and skipped_count is above zero |
| A fact refines an existing memory | The merged memory is in memories and updated_count is above zero |
Each call still costs one memory credit.
See it in code
This sample sends the same sentence twice to a Deep Search app. It prints the counts that the result reports.
import os

from smritea import MemoryScope, SmriteaClient, SmriteaError

client = SmriteaClient(
    api_key=os.environ["SMRITEA_API_KEY"],
    app_id=os.environ["SMRITEA_APP_ID"],
)
alice = MemoryScope(actor_id="alice", actor_type="user")
text = "Alice is vegetarian and loves hiking"

try:
    for attempt in (1, 2):
        result = client.add(text, scope=alice)
        print(
            attempt,
            len(result.memories),
            result.facts_extracted,
            result.skipped_count,
        )
except SmriteaError as e:
    print(e.http_status, e.code, e.request_id)
Expect the first call to report new memories. Expect the second call to report skipped facts, because Smritea already holds them. The exact counts depend on how the language model splits the sentence.
Learn more
The docs page How Smritea stores memory lists every field of the add result. The limits page explains what each call costs.
Related posts
Time-aware memory: ask what was true at one moment
A time-aware memory has a validity window. Learn how Smritea sets the dates and how valid_at, from_time and to_time filter a search.
Memory scoping: keep each user's and agent's memories apart
A scope says who a memory is about and which conversation it came from. Learn the six scope fields and how search combines them.
Smritea search methods and rerankers: which to pick
Smritea has three search methods and six rerankers. Learn what each does, what it costs in credits, and which limits apply.